The practical answer
Check robots.txt and page indexing directives before launch so private previews stay protected and the intended public pages remain available to search. Use this guide to choose a manageable first change, check the evidence behind it and connect the work to the customer journey. The examples are illustrative planning exercises, not reports of client results.
For implementation support, explore our technical SEO services.
Separate crawl control from indexing intent
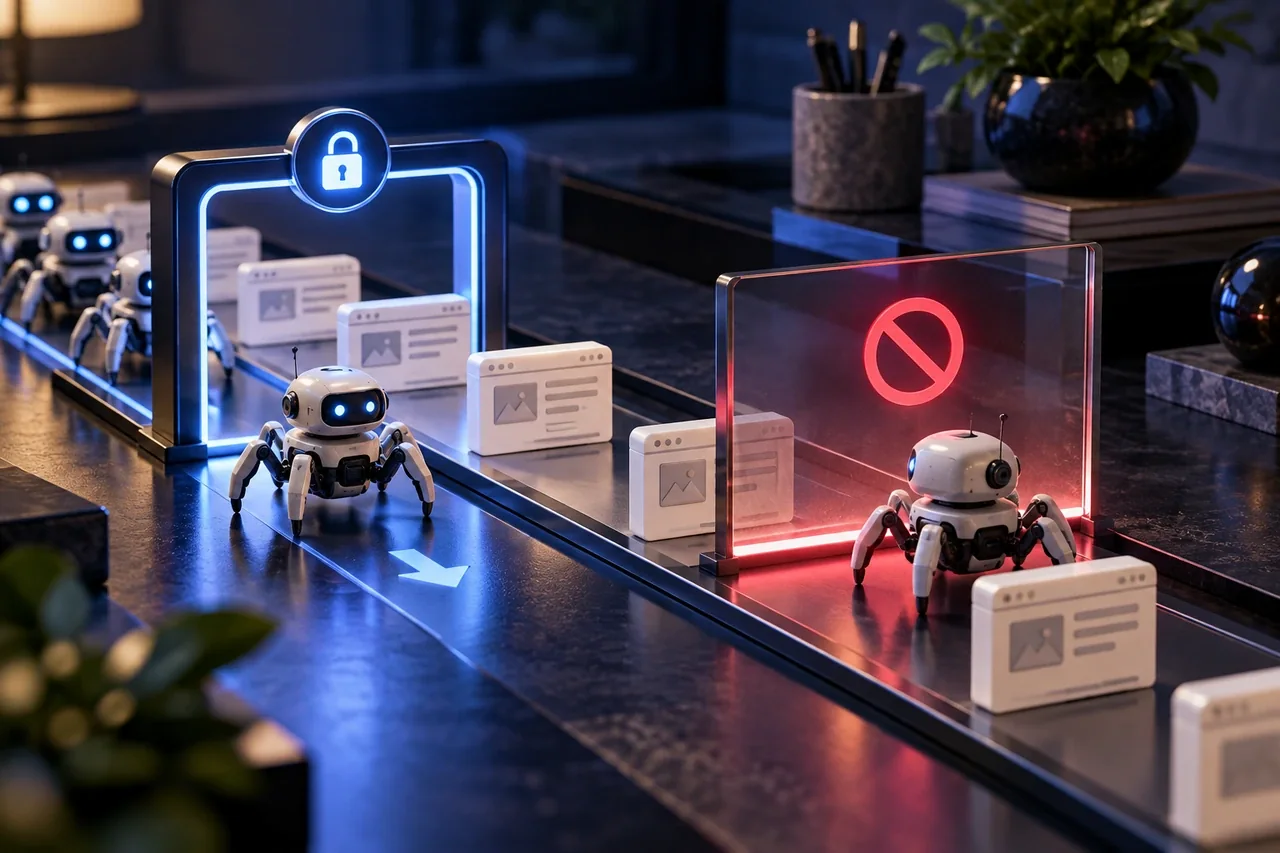
Robots.txt provides crawl instructions for participating crawlers, while page indexing directives communicate whether a page should appear in search. They serve different roles and should not be treated as interchangeable privacy controls. Understand the intended behaviour before editing either file. A private preview may need access restrictions as well as indexing precautions. Do not assume that a robots rule makes confidential information safe from people who know the URL.
Document preview and production policies
Write down which environment should remain private and which public routes are intended for discovery. Keep those decisions explicit in the export or deployment workflow. Copying a preview to production can carry a broad crawl block or noindex metadata into the live website. The opposite mistake can expose a temporary copy that was never meant to be public. Review the actual environment, domain and audience before changing the policy.
Inspect representative pages and the root file
Open the public robots.txt and inspect the delivered metadata or response headers for important service pages and articles. Check more than the homepage because templates can apply different rules to different page types. Confirm that the file is served from the intended host and that old server-level rules do not conflict with the page. Automated checks are useful, but a direct review of representative routes helps catch incorrect assumptions about the deployment.
Avoid hiding important resources unintentionally
A broad rule can affect pages or assets needed to understand the site. Review the purpose of each disallow path rather than copying an unrelated configuration. Keep enquiry endpoints and private runtime routes separate from public content, and protect sensitive server files through the hosting configuration. Robots instructions are not an access-control system. A sensible crawl policy should complement, not replace, proper server security and clear page-level indexing intent.
Verify the policy after deployment changes
Hosting migrations, plugins and build scripts can rewrite robots files or metadata. Add checks to the release process and revisit them when changing environments. If the public site was unintentionally excluded, correct the actual source of the directive and use supported inspection tools to review processing. Do not promise immediate indexing after the correction. Search systems need to revisit pages and make their own decisions about inclusion.
A focused implementation example
Imagine a private preview whose pages correctly contain noindex metadata. The public export should deliberately switch those page directives to the approved public policy while leaving the private preview unchanged. If a broad disallow rule is copied accidentally, the launch check should identify it before promotion begins. The example is about configuration consistency; correcting a directive does not guarantee that every page will be indexed or rank for a chosen query.
Measure the change before expanding it
Confirm the final public responses immediately, then use available search-console inspection tools to monitor important URLs. Keep a note of when the policy changed and which files were deployed. Do not interpret the absence of immediate search results as proof that the correction failed. Review access, content, internal discovery and the overall website alongside indexing directives. A complete diagnosis needs more than one robots setting.
Write the intended policy in plain language first
List which parts of the website should be public, which should remain private and which utility routes do not belong in search. This decision needs business and technical agreement before editing files. A launch checklist is easier to verify when it states the intended result rather than only naming a robots directive.
Keep the private preview and public upload policies separate. A review environment may intentionally exclude crawling, while published service and article pages should follow the approved public policy. Label each export clearly so a protective preview setting is not accidentally deployed as the permanent configuration of the live business website.
Distinguish discovery, crawling, indexing and access
These describe different behaviours and should not be treated as interchangeable controls. A crawler instruction does not create authentication, and a page indexing preference does not necessarily prevent a person from opening the URL. Sensitive information requires an appropriate access mechanism rather than reliance on a public robots file.
When a page should not appear in search, consult current official guidance on the relevant indexing control and ensure the crawler can encounter the directive where required. Avoid combining settings by guesswork. Explain the intended outcome to the developer and verify what the server actually returns.
Check the root file and representative page responses
Inspect the robots file at the root of the actual public host, not just a local copy inside a project folder. Review its rules and any applicable server-level headers. Then check representative service, category and article documents for indexing directives. Different templates can produce different results.
Include a freshly opened session and the final hostname after redirects. Cached assets or a staging URL can disguise a configuration mismatch. Keep the observed response with the launch record so the team knows what was verified. A screenshot of the page design cannot establish its crawl or indexing policy.
Protect utility endpoints without hiding necessary resources
Review API, administrative and configuration routes according to their actual function. They may need server access controls or separate protection. Do not assume that a disallow line is sufficient to keep configuration secrets private. Sensitive files should not be publicly served in the first place.
At the same time, avoid broad rules that unintentionally block resources needed to understand public pages. Check the consequences for stylesheets, scripts and images where applicable. A policy should be specific enough to match the site’s architecture and reviewed again when that architecture changes.
Repeat the check after deployment changes
A new hosting setup, export script or domain configuration can alter the response even when the source page is unchanged. Make the indexing-policy check part of significant deployments. Confirm the public pages intended for discovery and the private routes intended for protection rather than assuming an earlier result still applies.
If a mistake is found, correct the verified configuration and record the change. Do not promise immediate disappearance or inclusion in search after an edit. Search systems have their own processing, and a technically correct policy is only one part of publication. Maintain the distinction between implementation and an observed search outcome.
Your action checklist
- Write separate preview and public indexing policies.
- Inspect robots.txt on the actual public host.
- Check metadata and headers on several page types.
- Protect server files with access controls, not robots alone.
- Repeat checks after migrations and deployment changes.
Common questions
Can robots.txt protect confidential pages?
No. It is not authentication or a reliable privacy boundary. Use appropriate access controls for private material. Crawl and indexing instructions should be configured separately according to the purpose of each environment.
How should this work be prioritised?
Prioritise a real obstacle for a valuable audience over a cosmetic change made only for a search score. Record the starting condition, the proposed correction and the person responsible. Review the affected page and enquiry journey after implementation. Search visibility and customer behaviour have several causes, so do not attribute every change to one edit or promise a particular ranking.
Further reading
Continue exploring technical seo
Investigate crawlability, indexing, performance and migrations with a focused technical workflow.
- Website speed and Core Web Vitals: a practical guide for business owners
- Website Redirect Audits: Protect Useful Routes During Changes
- Canonical Tags: A Practical Audit for Small Business Websites
- JavaScript SEO Checks for Small Business Websites
- HTTP Status Checks: Find Broken Pages and Misleading Error Responses
- Image Loading Priorities: Keep the First Screen Fast and Stable
Put the next step into practice
Discuss your website, target audience and business priorities with SEO Optimizer in Chennai.
Explore technical SEO audits and improvements →Discuss your project
Prepared by SEOptimizer editorial. Examples are illustrative; outcomes depend on the business, market and implementation. AI-generated editorial imagery illustrates the subject and does not depict actual customers, employees or client results.